New benchmark · arXiv 2602.00593

When vision is
not enough.

A visual question-answering benchmark of 1,000 expert-crafted questions on 4K+ real-world scenes — where every answer demands both fine-grained visual grounding and open-web knowledge search.

The accuracy gap
Gemini 3.1 Pro Best model · crop + search
51.7%
Open-source avg Qwen, GLM, Gemma · same setting
23.2%
TL;DR
The bottleneck has shifted.Not perception alone — query construction and retrieval recall dominate failures.
Search beats sight, but only together.Cropping triples in value when combined with web search (3.49× synergy).
Long-tail knowledge breaks everything.Local phone numbers, small business hours, niche product specs — unreachable.

The promise of VLMs runs into the messy last mile.

Picture a tour guide spotting a distant mountain and telling you its history. For humans this is automatic — effortlessly linking subtle visual cues with structured facts via broad knowledge. For modern Vision-Language Models, it remains nearly impossible. The challenge is not visual grounding or knowledge search alone, but their tight coupling.
— From the Pix2Fact paper, Section 1
01

Pixel-level grounding

Locate a small visual detail — a phone number on a sign, a logo on a tent, a book title spine-on — inside a 4K+ scene full of distractors.

02

Open-world retrieval

Using only that detail, formulate a query, search the open web, navigate to unstructured sources, and extract the right fact.

03

Their conjunction

Existing benchmarks test either one. Pix2Fact tests both at once — what real human assistance requires, and where today's models break.

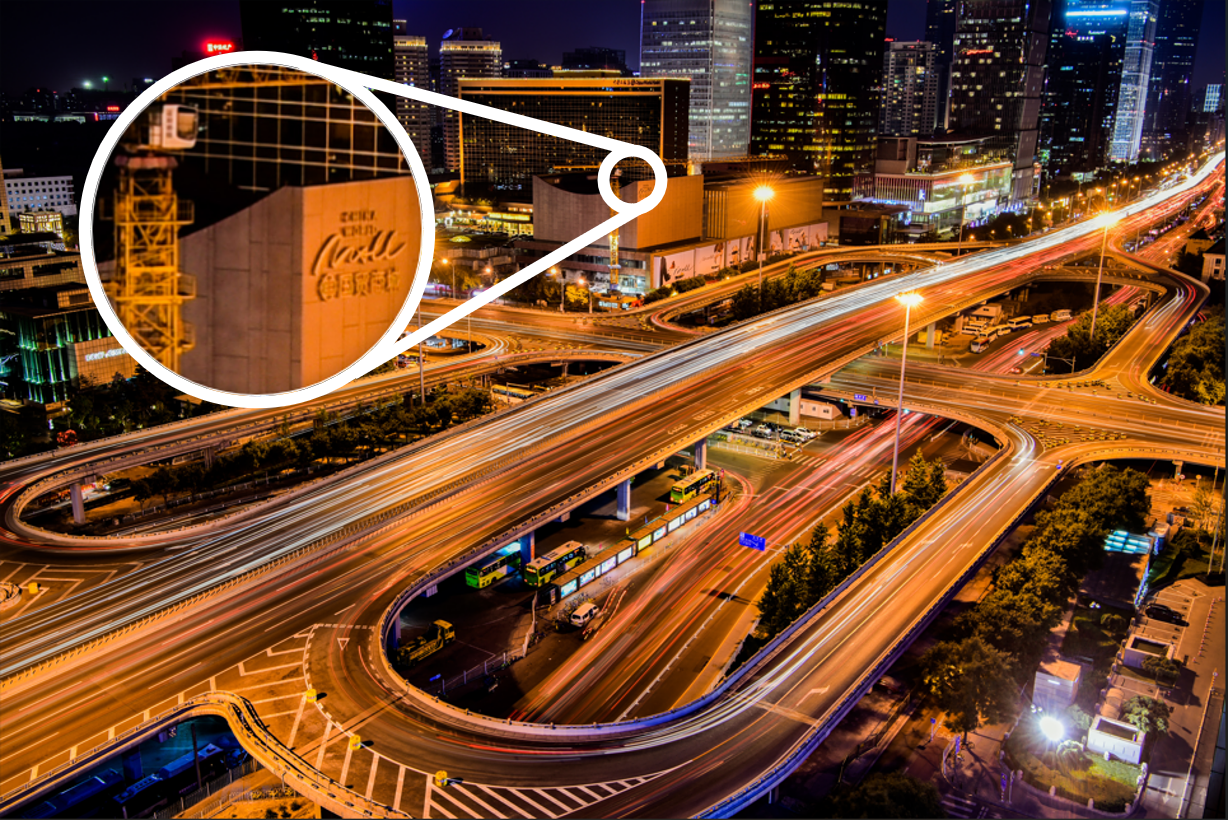
Figure 6 · Traffic & Infrastructure
Highway aerial · mall behind scaffolding
(replace with 4K original)
A real Pix2Fact question
A tourist might naturally ask:
"The building behind the scaffolding is a mall. Which number should we call for leasing inquiries to open a clothing store there?"
Correct answer
(86 10) 6505-6688
What a model has to do: get past the foreground roads, through the scaffolding, read the sign, identify the specific mall, then navigate its website to the leasing page — a chain general search engines rarely surface directly.
Why this is hard · the 5 things a model must do, in order
1
Locate the right building

Past foreground roads & distractor buildings.

SPATIAL · GROUNDING
2
Read tiny signage

OCR the mall name from behind scaffolding.

FINE OCR
3
Identify which mall

Disambiguate among real-world entities.

ENTITY LINKING
4
Find the official site

Construct a query that surfaces the right page.

QUERY · RETRIEVAL
5
Extract the contact

Navigate to leasing page, isolate the number.

NAVIGATION · EXTRACT
Eight scenes of everyday life.

1,000 questions across categories drawn from the visual texture of daily life. Mean resolution 21.1 MP · 78% exceed 15 MP · max 77.7 MP.

Street scene with people · Times Square
01 · 19.3%

Street scene with people

193questions
Storefronts & street facades · Paris alley
02 · 14.4%

Storefronts & facades

144questions
Retail & commercial interior · IKEA
03 · 12.9%

Retail & commercial interior

129questions
Traffic & infrastructure · highway
04 · 12.5%

Traffic & infrastructure

125questions
Markets & outdoor vendors · flower stall
05 · 11.1%

Markets & outdoor vendors

111questions
Public & cultural interior · library
06 · 10.5%

Public & cultural interior

105questions
Landmarks & attractions · Potala Palace
07 · 10.3%

Landmarks & attractions

103questions
Cityscape & aerial · Shanghai skyline
08 · 9.0%

Cityscape & aerial

90questions

One real question per scenario — try them yourself.

These are the eight representative examples from the paper (Figures 6–13). Each was crafted by a PhD annotator and requires both fine-grained visual grounding and external web search to answer.

Traffic & infrastructure · highway aerial
Traffic & Infrastructure
PAPER · FIG 6
The building behind the scaffolding is a mall. We want to open a store for our clothing brand there. Do you know which number we should contact for leasing inquiries?
Answer (86 10) 6505 6688
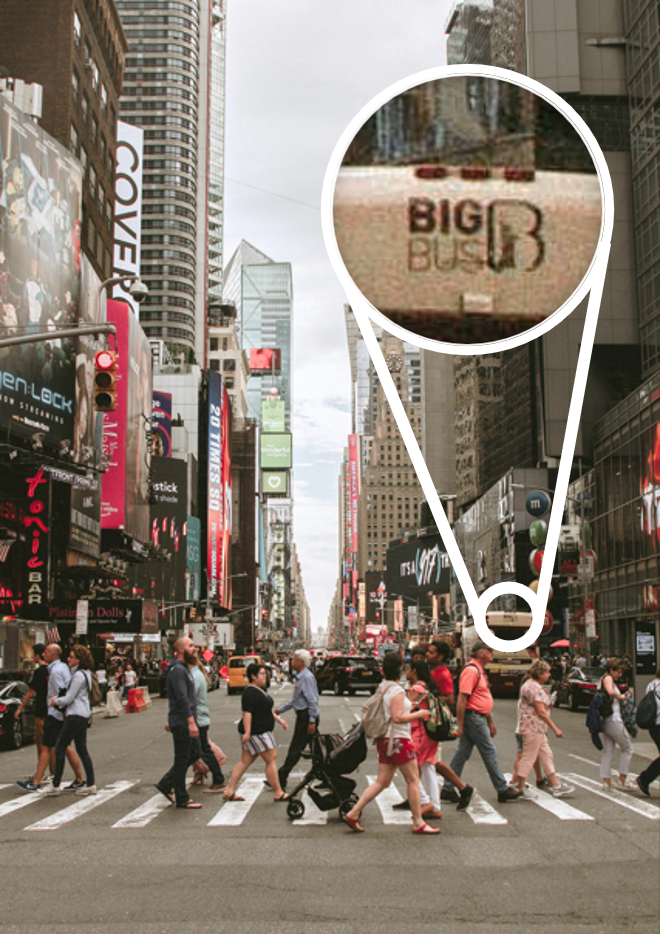
Street with people · Times Square
Street Scene with People
PAPER · FIG 7
If I want to take the bus on the right in this picture for a one-day tour of the city, what is the lowest official website ticket price in USD?
Answer $48
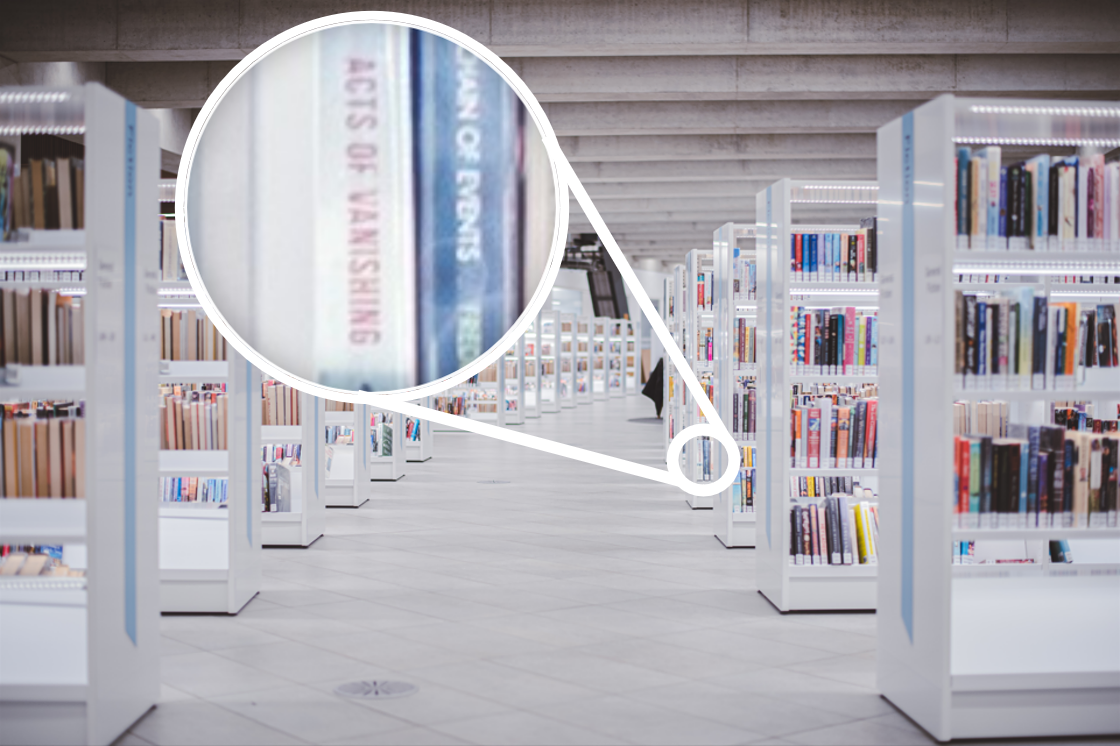
Public & cultural interior · library
Public & Cultural Interior
PAPER · FIG 8
Identify the name of a book on the bookshelf that starts with A and ends with G. I have a book ready for publication and want to contact the publisher of this book. What is the phone number of this publisher in the UK?
Answer +44 20 3122 6000
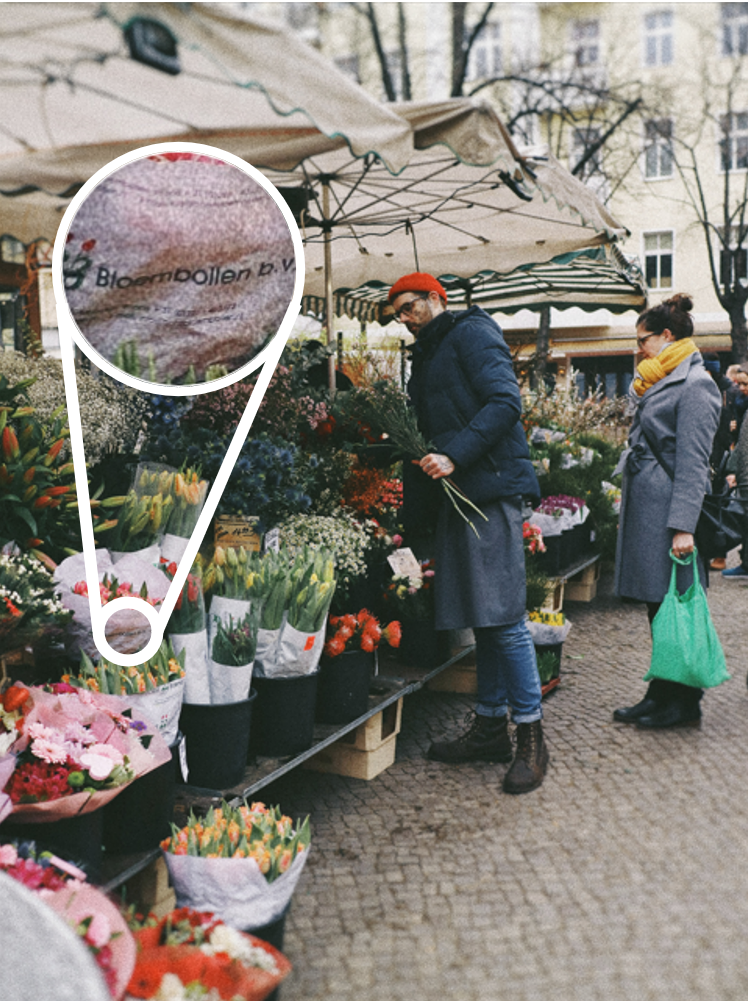
Markets & outdoor vendors · flower market
Markets & Outdoor Vendors
PAPER · FIG 9
Next week is my friend's graduation ceremony, and I would like to prepare a bouquet for her. What are the opening hours of the flower brand store shown in the image, excluding Saturdays and Sundays?
Answer 08:00 – 17:00
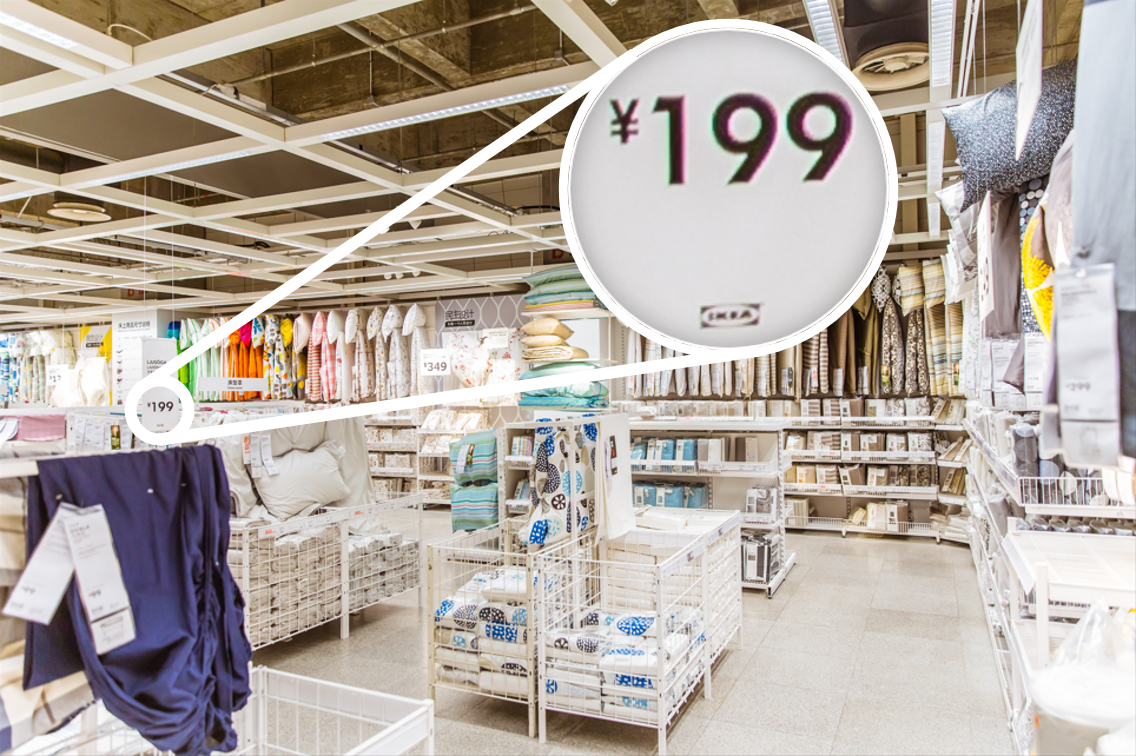
Retail & commercial interior · IKEA
Retail & Commercial Interior
PAPER · FIG 10
The store's logo is right under the white tag on the left of the photo. I heard that the quality of this brand's daily necessities is good. I want to buy a thermos on the Chinese official website of this brand. What is the capacity (in liters) of the most expensive thermos?
Answer 1 Liter
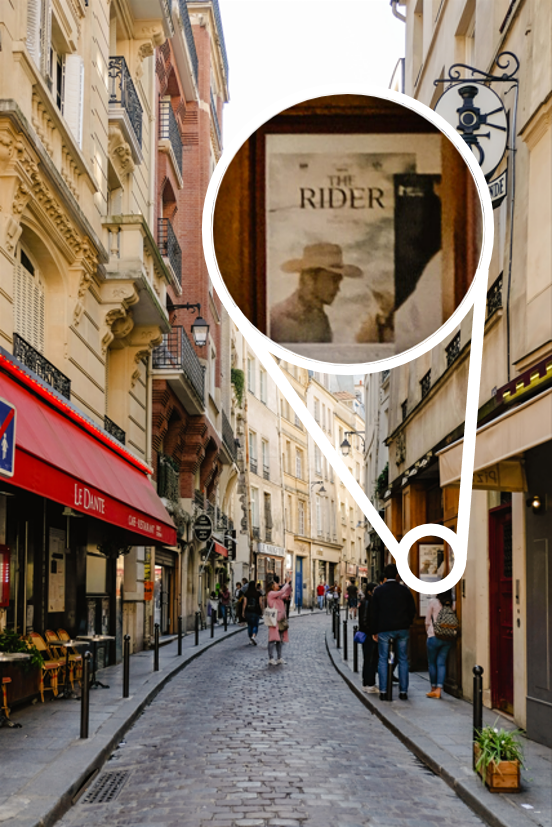
Storefronts & street facades · Paris alley
Storefronts & Facades
PAPER · FIG 11
I was chatting with a friend about movie poster designs, and when I came across this picture, I got curious about who the director is. I'd like to know which of this director's films is second on Rotten Tomatoes?
Answer Songs My Brothers Taught Me
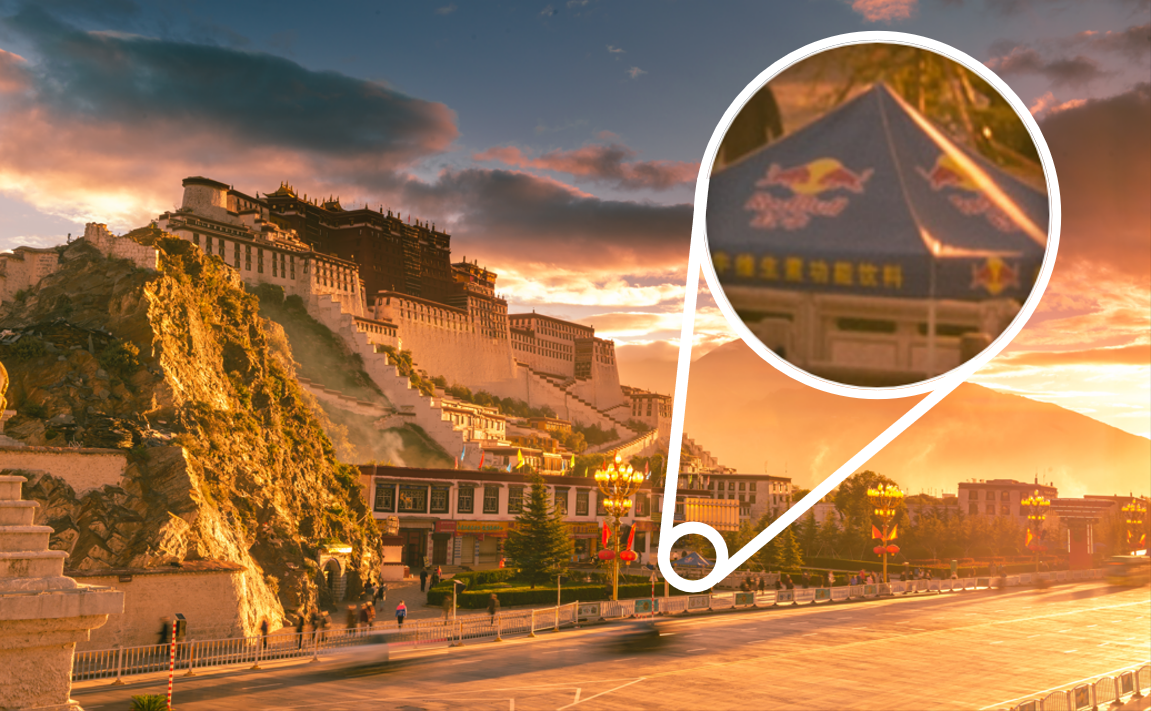
Landmarks & attractions · Potala Palace
Landmarks & Attractions
PAPER · FIG 12
The red logo on the blue tent in the photo belongs to an energy drink brand. I'm looking to contact their Beijing branch about becoming a distributor. Could you tell me what number I should call?
Answer 010-85288029-8010
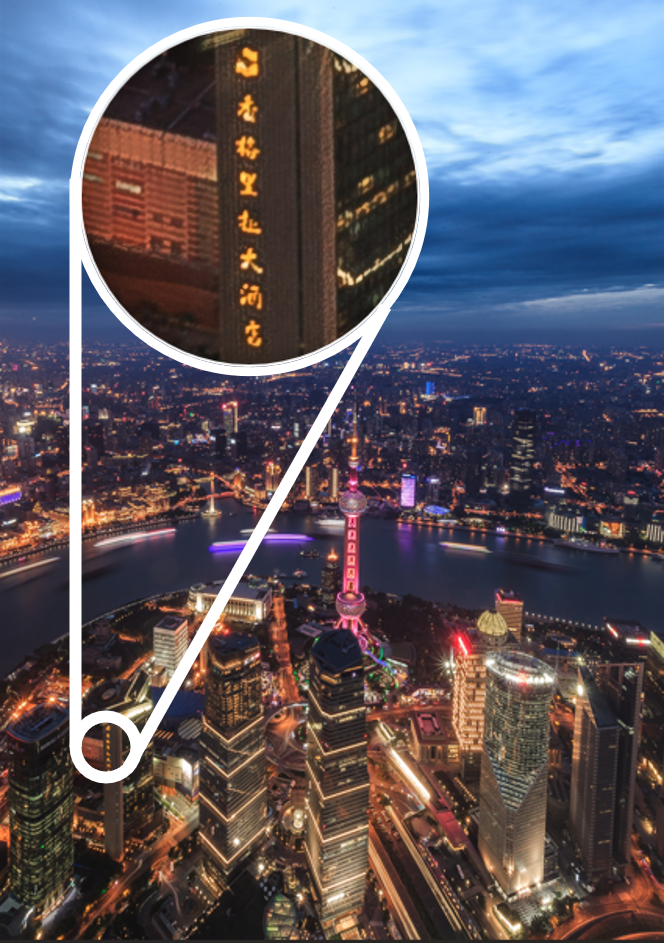
Cityscape & aerial · Shanghai skyline
Cityscape & Aerial
PAPER · FIG 13
Identify the vertical text on the building on the left in the picture, which is the name of a hotel. Our company's annual meeting requires booking a banquet venue of more than 1,000 square meters. How many event rooms are available for us to choose from at this hotel?
Answer 6 rooms
1 / 8
Quality assurance · Section 3.2

How each (Q, A) is built — industrial-grade quality.

Every question survives a multi-stage authoring pipeline with three-tier PhD review. Average 35–40 minutes of expert labor per validated item — and ~38% of drafted items are rejected during quality control.

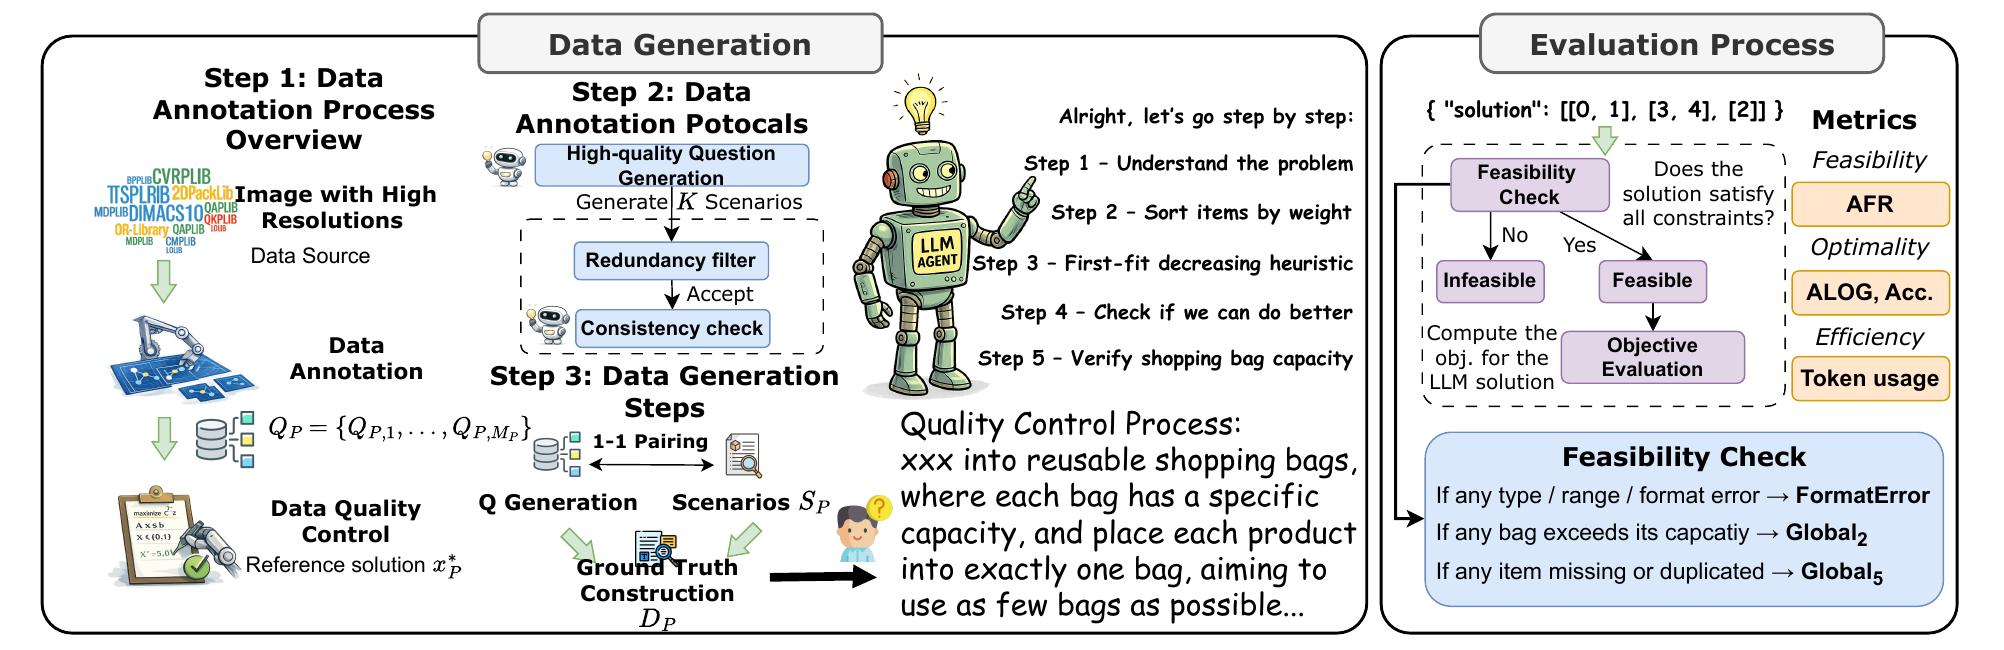
Pix2Fact data generation and evaluation pipeline
Figure 2 · Data generation and evaluation pipeline. Source images → expert annotation → 1-1 question pairing → ground-truth construction → feasibility check → objective evaluation against three metric families.
/ 01

Source

Royalty-free platforms (Unsplash, Pexels, Pixabay). ≥2 MB · 4K–8K · CC-licensed.

21.1MPMean resolution
/ 02

Filter & categorize

Composition review by domain experts. Eight scene categories drawn from daily-life visual texture.

8catsScene taxonomy
/ 03

Author Q & ground-truth

Each Q anchored to a unique pixel-level cue + 1–3 evidence URLs. Author logs reasoning chain.

1–3URLsEvidence sources
/ 04

Three-tier review

Author → peer reviewer → senior PhD adjudicator. Redundancy filter + consistency check at every gate.

38%Reject rate
1,000
Validated questions
~600h
Total expert labor
100%
PhD-author verified
3×
Independent review layers

Ten frontier VLMs · the ceiling sits at 51.7%.

Each model is evaluated under four conditions formed by two binary axes: original vs. expert-cropped image, and no-search vs. with web search. C4 (cropped + search) is the best-case ceiling.

14pp

Closed > open. Top three closed-weight models average 14 percentage points above the open-source group at C4.

3.49×

Search amplifies cropping. When combined with web search, expert cropping triples in value across all models.

48pp

Headroom remains. Best score (51.7%) still leaves a 48-point gap to a perfect score — the benchmark is far from saturated.

Testing a new model? We welcome submissions — get in touch and we'll evaluate it and add it to the board.

#
Model
C1orig · no search
C2orig · search
C3crop · no search
C4crop · search
Avg
1
Gemini-3.1-Pro closed
18.4%
42.4%
21.0%
51.7%
33.4%
02
Gemini-2.5-Pro closed
14.6%
29.1%
18.6%
39.0%
25.3%
03
GPT-5.4 closed
8.5%
17.9%
14.5%
32.9%
18.5%
04
Grok-4.20 closed
4.4%
22.3%
7.3%
38.8%
18.2%
05
Claude Opus 4.7 closed
13.3%
N/A
16.3%
N/A
14.8%
06
Qwen3.6-27B open
4.7%
16.8%
4.9%
26.2%
13.2%
07
GLM-4.6V open
2.9%
11.4%
6.6%
23.9%
11.2%
08
Doubao-2.0 closed
8.0%
8.6%
12.5%
15.1%
11.1%
09
Doubao-1.8 closed
7.2%
10.6%
8.4%
17.2%
10.9%
10
Gemma4-31B open
2.8%
8.2%
6.2%
19.6%
9.2%
1
Gemini-3.1-Pro
33.4%
closed
C1
18.4%
C2
42.4%
C3
21.0%
C4
51.7%
2
Gemini-2.5-Pro
25.3%
closed
C1
14.6%
C2
29.1%
C3
18.6%
C4
39.0%
3
GPT-5.4
18.5%
closed
C1
8.5%
C2
17.9%
C3
14.5%
C4
32.9%
4
Grok-4.20
18.2%
closed
C1
4.4%
C2
22.3%
C3
7.3%
C4
38.8%
5
Claude Opus 4.7
14.8%
closed
C1
13.3%
C2
—
C3
16.3%
C4
—
6
Qwen3.6-27B
13.2%
open
C1
4.7%
C2
16.8%
C3
4.9%
C4
26.2%
7
GLM-4.6V
11.2%
open
C1
2.9%
C2
11.4%
C3
6.6%
C4
23.9%
8
Doubao-2.0
11.1%
closed
C1
8.0%
C2
8.6%
C3
12.5%
C4
15.1%
9
Doubao-1.8
10.9%
closed
C1
7.2%
C2
10.6%
C3
8.4%
C4
17.2%
10
Gemma4-31B
9.2%
open
C1
2.8%
C2
8.2%
C3
6.2%
C4
19.6%

Search amplifies cropping — synergy ratio 3.49×

Average gain across 9 models · ∆V = cropping gain · ∆S = search gain

∆Vno searchCropping alone
+3.2
+3.2 pp
∆SorigSearch alone
+10.6
+10.6 pp
∆Vwith searchCropping when searching
+10.8
+10.8 pp
∆ScropSearch when cropped
+18.3
+18.3 pp
∆TotalC1 → C4 · full lift
+21.4
+21.4 pp

Models fail — but they fail in different ways.

A 121-case audit reveals heterogeneous bottlenecks. The dominant breakage has shifted upstream — into query construction and retrieval recall, not perception or reasoning.

Claude
87%

Knowledge bottleneck

Search executes correctly, but the long-tail fact never surfaces. Produces a confident but slightly wrong answer.

Qwen
63%

Tool-use breakdown

Fails to invoke the search tool at all. A fundamental gap in agentic behavior, not query formulation.

All models
43%

Query construction

The most common search-stage error — queries built on misidentified entities. Only 17% are integration issues.

Cropping
100%

Crop rescue rate

Expert cropping resolves all 18 grounding failures. 72% involve wrong attention, not just low resolution.

Two real failure cases

Sourced from the paper's deep-dive analysis.

Case 1 · Index 923-1 · Wrong attention
Attention re-localization
On the right side of the image, what brand are the sneakers the woman is wearing?
Pixel-level grounding · what the model has to find
Original scene (C1) High resolution · 4K+
Expert
crop
Expert crop (C3) Target region
✕
Without cropping
Model attends to a visually similar but wrong object: "She is wearing black sneakers with a distinctive white 'N' logo on the side, identifying the brand as New Balance."
✓
With expert crop
Attention re-localizes: "the short-haired woman is wearing black sneakers featuring a distinctive white 'swoosh' logo."
Ground truth Nike
Case 2 · Index 415-1 · Confident-but-wrong
Near-miss factual error
For the well-known clothing brand in the picture, how many stores did it have worldwide in fiscal year 2024?
Pixel-level grounding · the logo on the storefront
Original scene (C1) High resolution · 4K+
Expert
crop
Expert crop (C3) Target region
✕
Claude's answer
"According to Fast Retailing's annual report for FY2024, Uniqlo had approximately 2,501 stores worldwide, including around 800 in Japan and over 1,700 internationally."
✓
What actually happened
Brand correctly identified. Evidence correctly retrieved. But the final number is fabricated as a "reasonable-sounding" approximation — the actual figure is 2,495, a 6-store difference that breaks the question.
Ground truth 2,495 stores

Three bottlenecks now define the next frontier.

Pix2Fact shows that the cap on real-world visual assistance is no longer perception alone. Models need fine-grained grounding and deliberate, multi-step retrieval that survives the messy long tail of the open web.